Updated September 20, 2026 — deep-dive on the September 18, 2026 announcement
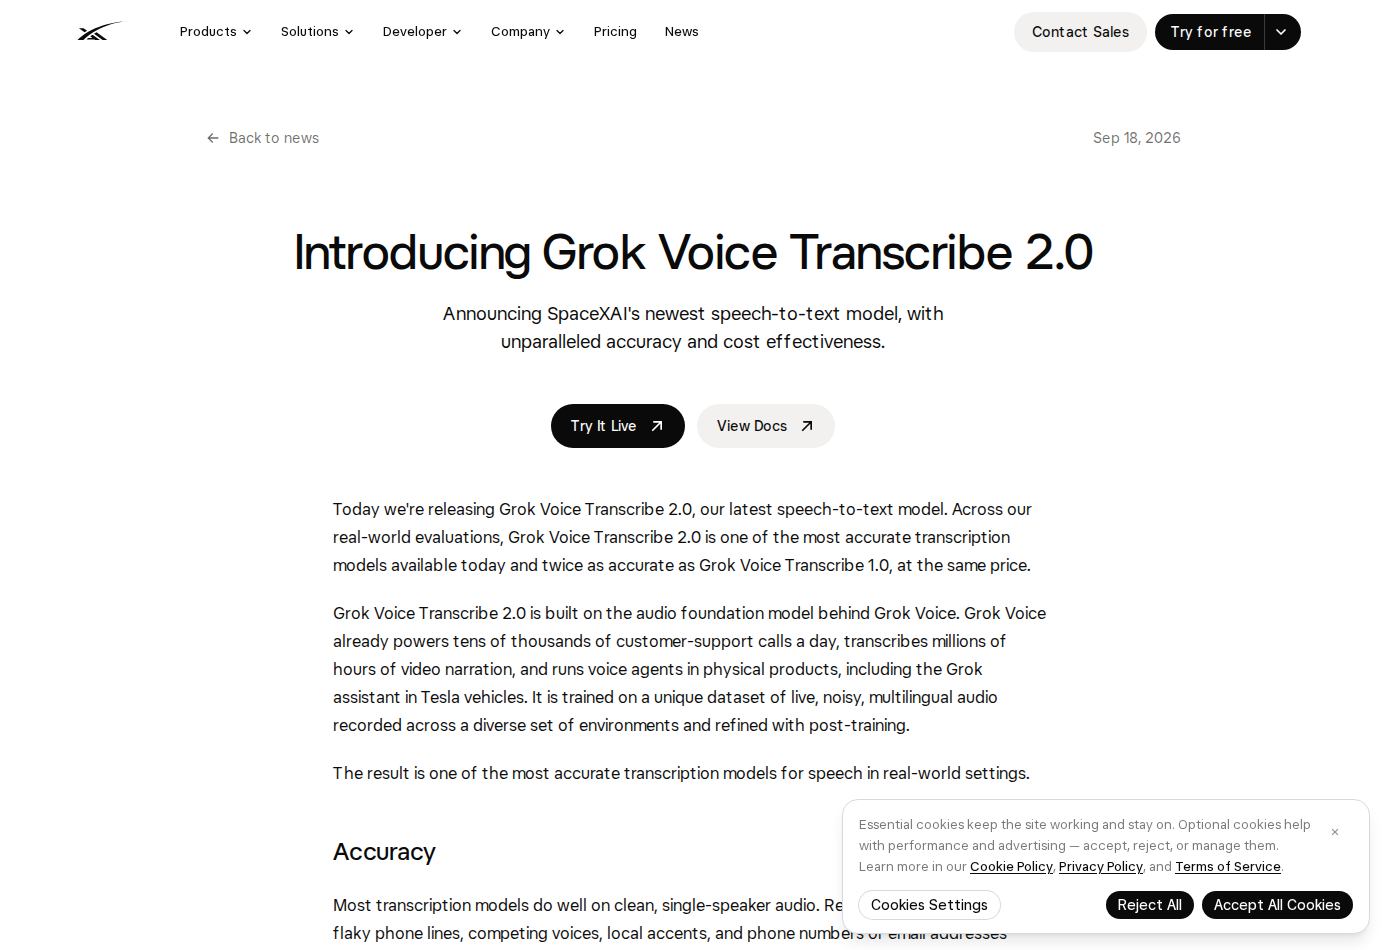
Every podcaster, course creator, and video producer knows the bottleneck: you have an hour of great audio and no text. Transcription has quietly become the connective tissue of modern content operations — feeding captions, show notes, articles, translations, and increasingly the AI tools that sit downstream of your recordings. On September 18, 2026, xAI raised the stakes by launching Grok Voice Transcribe 2.0, a speech-to-text model the company says ranks first for accuracy among 32 streaming models on the public Artificial Analysis leaderboard — at twice the accuracy of its own predecessor, for the same price. We read the full announcement so you don't have to. Here is what shipped, what the numbers actually claim, where Arabic and other languages stand, and whether this belongs in your production stack.
What launched, exactly?
Grok Voice Transcribe 2.0 is a speech-to-text model available through the xAI developer console. The announcement makes a point worth pausing on: it is built on the same audio foundation model that powers the entire Grok Voice stack — the system that handles tens of thousands of customer-support calls a day, transcribes millions of hours of video narration, and runs the Grok assistant inside Tesla vehicles. In other words, this model was trained on live, noisy, real-world audio — flaky phone lines, competing voices, local accents — rather than clean studio recordings. That is precisely the kind of audio most creators actually have.
The release announcement bundles three claims: leaderboard-topping accuracy on public benchmarks, wins across four internal evaluation sets drawn from production traffic, and a production-grade feature set (word-level timestamps, speaker diarization, multilingual support) that positions it against dedicated transcription vendors rather than hobby tools.
The numbers: what xAI claims, precisely
- #1 among 32 streaming models for accuracy on the public Artificial Analysis leaderboard — the reference board used across the industry to compare audio models on standardized tests.
- 2x accuracy over Grok Voice Transcribe 1.0 at the same price — stated verbatim in the announcement, and notable because capability jumps usually arrive with price jumps attached.
- Four internal evaluation sets built from real production traffic: 8 kHz telephony audio from support calls, conversations with Grok, spoken credentials (phone numbers, emails, account codes), and short multilingual voice commands across 19 languages. The new model beats 1.0 on all four — and on telephony, it leads every model xAI tested.
- Short phrases: word error rate fell from 20.6% to 6.8% versus the previous generation. Short commands are the hardest case — with almost no context, the model cannot guess; it has to actually hear.
The announcement's accuracy chart names its competition directly: ElevenLabs Scribe v2 and Deepgram Nova-3, alongside the older Grok generation. That is the honest competitive set for serious transcription in 2026 — and it is the set you should benchmark against with your own recordings.
The feature set: what separates this from "just a transcript"
The gap between a good model and a usable production tool lives in the details. From the announcement:
- Batch and streaming: transcribe recorded files and URLs, or plug into a live audio stream in real time.
- Word-level timestamps: every word carries precise start/end times plus confidence scores — the foundation for karaoke-style captions, subtitle alignment, and in-video search.
- Speaker diarization at no extra cost: label who said what inside the transcript, for free. For interview shows and panels, this is often the single most expensive line item with other vendors.
- Multichannel transcription: up to 8 independent channels per request — conferences, field recordings, meetings with per-speaker microphones.
- Key term biasing: pass up to 100 domain terms per request — product names, brand spellings, technical vocabulary — so the model transcribes them correctly instead of guessing.
- Text formatting: numbers, dates, currencies, phone numbers, and email addresses come back in written form, not as a phonetic mess.
- Filler word removal: optionally strip "um" and "uh" from the final transcript.
- Smart turn detection: endpoint detection for builders wiring transcription into voice agents.
And the upgrade path is frictionless if you are already on xAI's Speech-to-Text API: existing integrations get the accuracy bump with no code changes — the model slots into the same interface.
Languages: the honest section
The announcement states that the model "transcribes dozens of languages, detects the language automatically, and follows mid-recording switches in a single pass," and that multilingual accuracy is its largest improvement over the 1.0 generation. The short-phrase evaluation covered 19 languages. What it does not do is publish per-language numbers — so if your production is in Arabic, Hindi, Portuguese, or any language outside the English-heavy internal sets, treat the leaderboard as a signal, not a guarantee.
Three details do matter for non-English producers. First, training on "live, noisy, multilingual audio recorded across a diverse set of environments" is exactly the profile of real-world non-studio content. Second, mid-recording language switching in one pass matches how bilingual creators actually speak — the Arabic-English, Hindi-English, or Spanish-English code-switching that breaks so many tools is here a first-class behavior. Third, key term biasing gives you a lever: feed in the proper nouns, product names, and specialized vocabulary of your niche, and the model gets them right on purpose rather than by luck.
Our standing advice for any new transcription model applies doubly here: run your own test protocol (we publish one below) before migrating a production workflow.
The proof point: Atlassian Loom
The announcement closes with a named customer: Atlassian Loom, the screen-recording platform used by teams worldwide, found Grok Voice Transcribe 2.0 more accurate than their existing solution for transcribing Loom videos — and adopted it. The line that should catch every content operator's eye is not about accuracy at all: "Accurate transcripts open up new AI workflows: record an action plan in Loom, pipe the transcript into Cursor, and it makes the code updates directly."
Read that again. The transcript is no longer the product — it is the fuel. The same logic applies to every content business: one accurate transcript becomes show notes, a newsletter section, an article draft, quote graphics, translations, and searchable archives. The model that produces that transcript just got materially better and cheaper, which quietly lowers the cost of your entire downstream pipeline.
What this means for content creators
- Reels and shorts scripts from your own voice: record the idea while walking, get timestamped text back, and turn it into a script, article, or newsletter item — instead of writing from a blank page.
- Podcast and interview transcripts with free diarization: the most expensive feature at traditional vendors is included, which changes the math for interview shows and multi-guest panels.
- Captions that align properly: word-level timestamps with confidence scores are what make frame-accurate subtitles possible without manual nudging.
- Conference and event coverage: 8-channel support turns a multi-mic event recording into separate clean transcripts per speaker.
- Better voice agents: if you are building a voice bot for your audience or customers, inbound transcription quality is the first bottleneck — see our coverage of the voice-agent wave in GPT-Live-1 in the API and Gemini 3.8 Live, plus our earlier deep-dive on Microsoft's MAI Transcribe 2.
How it stacks against the alternatives
| Dimension | Grok Voice Transcribe 2.0 | MAI Transcribe 2 (Microsoft) | ElevenLabs Scribe v2 | Deepgram Nova-3 | Open-source Whisper |
|---|---|---|---|---|---|
| Access | API via console.x.ai | Azure ecosystem | Commercial API | Commercial API | Self-hosted |
| Speaker diarization | Built in, no extra cost | Available in service | Plan-dependent | Available | Extra processing needed |
| Mid-recording language switch | Documented, single pass | Not headlined | Not headlined | Not headlined | Weak in practice |
| Timestamps | Per word + confidence | Available | Available | Available | Coarser granularity |
| Cost model | Same price as v1 (per-minute rate in console) | Azure pricing | Consumption | Consumption | Free but on your hardware |
Methodology note: competitor column entries come from the comparison chart inside xAI's own announcement and the vendors' public pages — not from our independent testing. Benchmarks are marketing until you run them on your audio; the table above tells you what to test, not what to believe.
Honest limits and caveats
- API only. There is no consumer upload-and-download app; you need a developer or an intermediary tool.
- Per-language numbers are unpublished. The leaderboard aggregates; it does not certify your language. Test before migrating.
- The exact per-minute price is not in the announcement. "Same price as 1.0" is the published claim; the live number lives in the developer console and can change.
- English dominates the internal evals. Three of the four internal sets are English; non-English performance may trail the headline numbers.
- Single-vendor dependency. If transcription is mission-critical to your pipeline, keep a fallback provider wired in.
A practical test protocol before you commit
- Prepare three representative samples: a clean studio recording, a real-world phone recording, and a noisy mobile clip. These are the three environments your content actually lives in.
- Include code-switching on purpose: add a segment where you mix two languages the way you naturally speak. This is the model's advertised strength — verify it on your accent.
- Use key term biasing: collect the 100 proper nouns and niche terms your previous tool got wrong, pass them in, and compare before/after.
- Measure what your audience notices: proper-noun accuracy, number accuracy (prices, phone numbers, dates), and leaked filler words — not the theoretical word error rate.
- Request timestamps and diarization once, and once without: find out whether your files actually need the premium features before you pay for them on every request.
Document the results in a simple table and re-run after every provider update. Audio models drift silently between versions; a quarterly re-test protects your output quality from slow decay.
The bigger picture: one piece of a voice stack
Grok Voice Transcribe 2.0 is not xAI's first move in audio — it is the newest layer in a stack that has been assembling all year, each date from xAI's own newsroom: the Grok Voice Agent API opened voice agents to all developers on December 17, 2025; Custom Voices added voice cloning from a short recording on April 30, 2026; Grok Voice Think Fast 2.0, their most capable speech-to-speech model, launched July 29, 2026; and now a transcription layer aimed directly at the specialist vendors. For creators, the competitive implication is simple: per-minute transcription prices keep falling while feature sets (diarization, timestamps, term biasing) keep getting bundled in. Whoever you choose, the direction of this market is in your favor.
Frequently asked questions
What is Grok Voice Transcribe 2.0?
It is xAI's speech-to-text model released on September 18, 2026, ranked first for accuracy among 32 streaming models on the public Artificial Analysis leaderboard, twice as accurate as its predecessor at the same price, with production features including free speaker diarization, word-level timestamps, up to 8 channels per request, automatic language detection, and mid-recording language switching in a single pass.
Does it support Arabic and other non-English languages?
The announcement says "dozens of languages" with automatic detection and mid-recording switching, and the short-phrase evaluation covered 19 languages — but no per-language scores are published, and the internal evaluation sets skew English. For Arabic or any specific language, run the test protocol above on your real recordings before making it your production transcription provider, and use key term biasing for proper nouns and niche vocabulary.
How much does it cost?
The announcement states the price is unchanged from Grok Voice Transcribe 1.0 but does not print the per-minute figure; the live rate is published in the xAI developer console (console.x.ai) and may be updated there. Calculate your real project cost from the console, not from the blog post.
How is this different from free transcription tools?
Free tools typically return raw text without reliable diarization, word-level timestamps, or language-switch handling, and they degrade quickly on noisy or telephony audio. This model was built specifically on messy real-world audio (support calls, in-car commands, overlapping voices) and treats the transcript as infrastructure — input for summaries, articles, translations, subtitles, and downstream AI tools, as the Atlassian Loom example in the announcement shows.
Do I need to be a developer to use it?
For direct API use, yes — or an intermediary tool that uploads files for you. If your actual goal is turning ideas into polished, publishable written content rather than wiring APIs, a creator platform like ArWriter does that end to end; the full tool set is here.
Sources
- xAI's official announcement: Introducing Grok Voice Transcribe 2.0 — primary source for every figure and feature in this article (September 18, 2026)
- xAI developer console — access and live pricing
- xAI newsroom pages for stack context: Grok Voice Agent API (Dec 2025), Custom Voices (Apr 2026), Grok Voice Think Fast 2.0 (Jul 2026)
- Related ArWriter coverage: GPT-Live-1 in the API and Microsoft MAI Transcribe 2
Accurate transcription was never the end goal — it is the doorway that turns one recording into ten pieces of content. Whichever model you standardize on, make sure the rest of your pipeline is ready to receive it: drafting, visuals, and scheduling in one place is exactly what ArWriter was built for.