Europe just entered the trillion-parameter club — and it's doing it with open weights.
On Tuesday, October 6, 2026, French AI lab Mistral announced Mistral Large 4, its largest and most capable model to date: a 1-trillion-parameter system (49 billion active per call) that the company says it will release as open weights "by the end of the month" — with API pricing that dramatically undercuts the American frontier.
The announcement landed on Mistral's official site and immediately shot to the top of Hacker News, largely because of what it represents: the first European model of this scale, trained entirely on the company's own European infrastructure, positioned explicitly as an alternative for work that US labs decline to do. Here's what's actually in the announcement, and what it means if you build content tools or run a text-heavy business.
What Mistral Large 4 actually is
Per the official announcement: a 1 trillion total parameter, 49 billion active mixture-of-experts model described as an "open-weight hybrid instruct-and-reasoning MoE," natively multimodal with image and text input. Mistral calls it, without hedging, "our largest and most capable model to date" — and, with typical company humor, nicknames it le Chonk.
The training details signal the scale of ambition: trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters, on the back of a €3 billion funding round the company describes as the largest equity round ever raised by a European technology company.
The two decisions that matter: open weights and price
Open weights, end of October. The announcement states plainly: "We will release the weights by the end of the month." For the trillion-parameter class — until now the exclusive territory of closed US systems — that's the headline. No license name has been published yet; that detail arrives with the weights, and it's the one to watch before anyone builds on it commercially.
Aggressive pricing. The API is available now in public preview on Mistral Studio at $1.36 per million input tokens and $4.18 per million output tokens. Those rates place it among the cheapest options in the frontier class — relevant to anyone whose product generates large volumes of text daily and feels every fraction of a cent.
Where it genuinely excels — and where it doesn't claim to
Credit where due: Mistral's announcement is unusually specific about what the model is good at, and creative writing is not on the list. The claimed strengths are:
- Cybersecurity — the flagship claim. 82% on a vulnerability reproduce-and-patch test, which Mistral calls the highest of any model, noting that Claude Opus 5.5 and GPT-6 Astra "score near zero" there because they refuse the tasks. 93% of Cybench challenges solved, and a top-five global position on the AA Cyber Index among open-weight models.
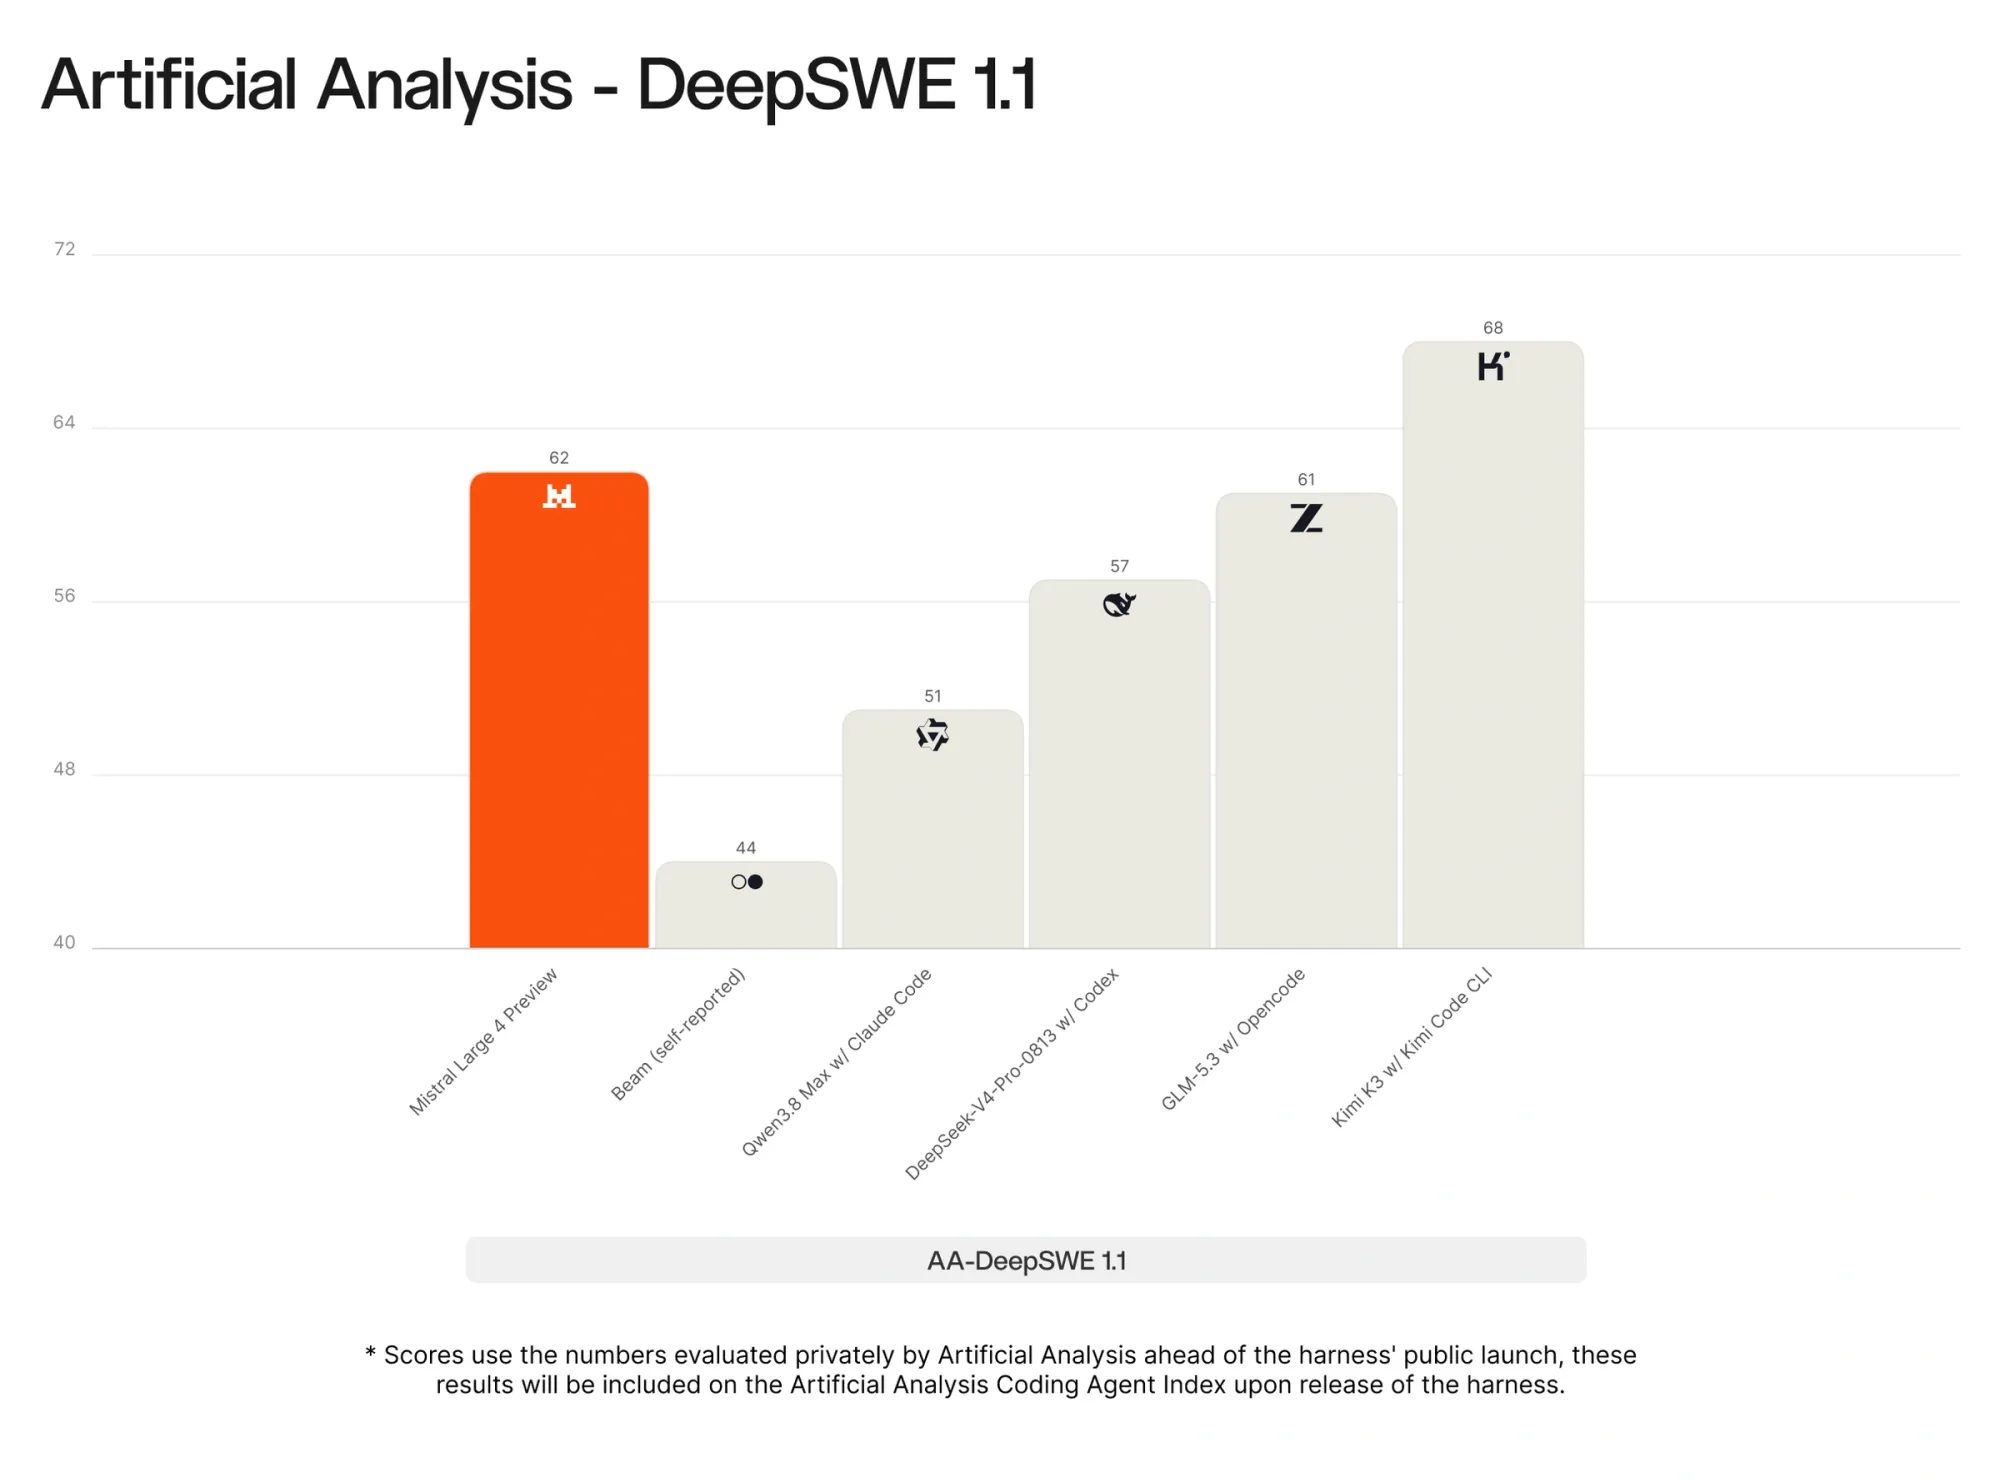
- Coding and agentic work. 61.7% on DeepSWE and 59.9% on AutomationBench, with the announcement placing it ahead of DeepSeek V4 Pro, Qwen 3.8 Max, and Kimi K3.
- Legal and financial knowledge work. Ahead of GPT-6 Astra on vals.ai legal and finance evals, and the leader among open-weight models on Harvey's Legal Agent benchmark.
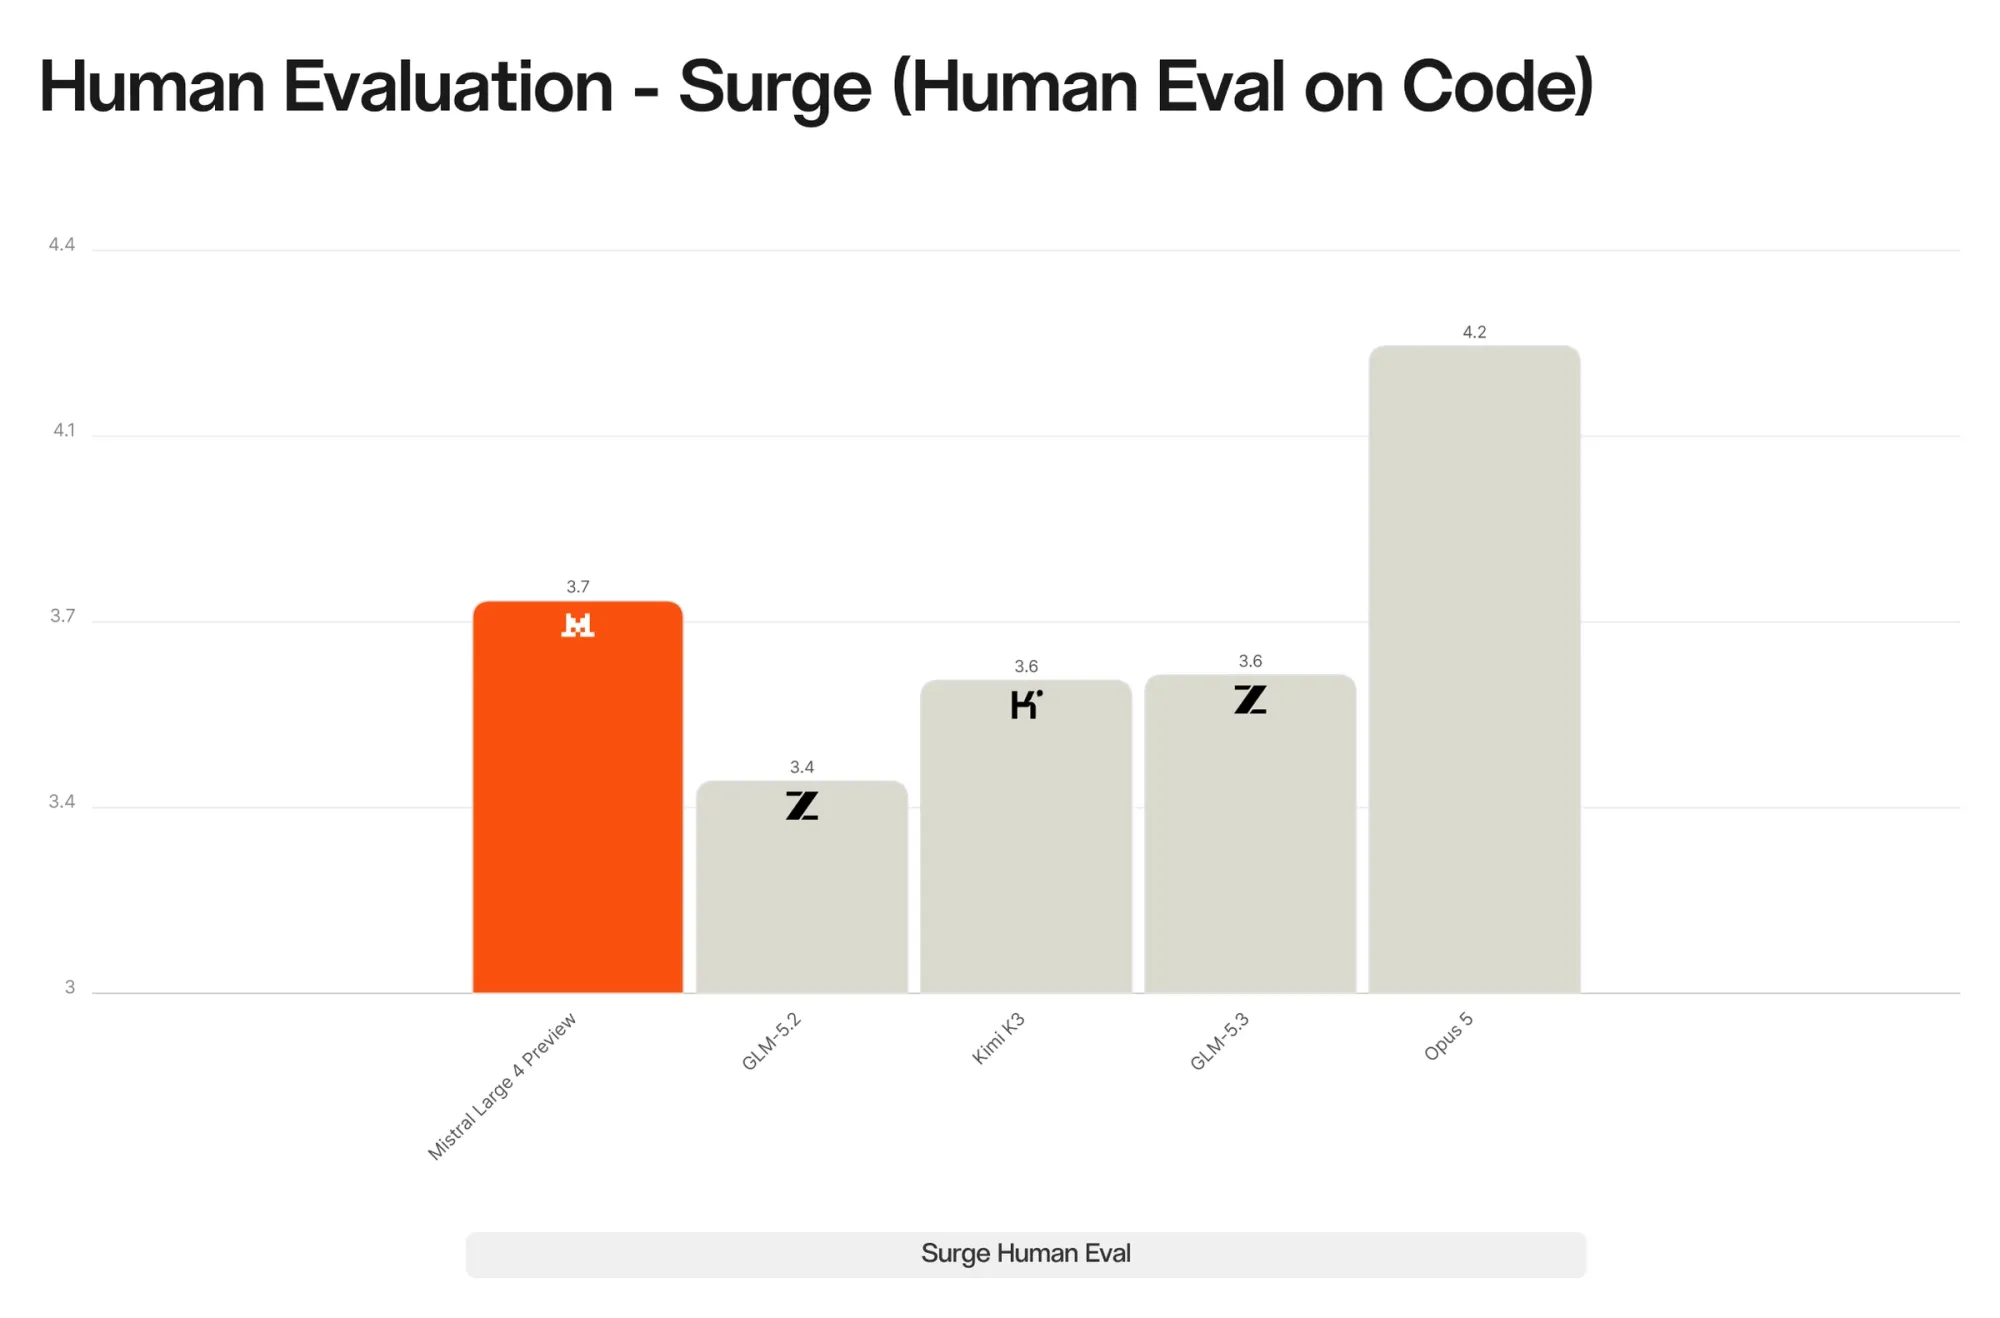
On human evaluation, the picture is honest rather than triumphant: in Surge's human eval on coding tasks, Large 4 ranked second of five at 3.74 out of 5 — ahead of Kimi K3 (3.59), GLM-5.3 (3.60), and GLM-5.2 (3.40), behind Claude Opus 5 (4.22). Read that as: near the front of the pack, at a fraction of the price, not an undisputed leader.
What this means if you build content — or content tools
- Text at volume gets cheaper. A million output tokens cost $4.18. If your service drafts product descriptions, reports, or localized copy in bulk, frontier-class capability at this rate widens your margins.
- A European answer for data-sensitive clients. Mistral operates a European deployment "end-to-end, independently of other digital service providers and under European law," with private-cloud and on-prem options. If your clients ask where their data is processed, this is suddenly a strong card.
- No vendor lock-in after month-end. Once the weights ship, expect the model to appear across providers and inference platforms — you're no longer tied to one company's pricing decisions.
- For creative writing: wait for independent testing. The announcement makes no claims about stylistic quality; its numbers are cyber, code, legal, and finance. If your content business lives or dies on tone and craft, benchmark it against your current stack before switching.
The language question
The announcement says training spans 160+ languages, including every official EU language — but it does not name Arabic or claim any specific level for it. We won't infer what isn't stated. For Arabic-language workloads, Mistral's most relevant commitment remains its separate partnership with Saudi Arabia's HUMAIN to develop Arabic-first models — a different track from Large 4, which we covered when it was announced. The practical test for Arabic arrives when the weights land and independent evaluations follow.
Honest limits
- The weights are not available today. "End of the month" is a promise in progress; any tool claiming to offer local Large 4 downloads right now is jumping the gun.
- It's a public preview. Fine for evaluation and pilots; think twice before migrating production-critical services.
- No context window was published, and full architecture and post-training details are promised alongside the weights release.
- Self-hosting will be heavy. 49 billion active parameters put comfortable local deployment out of reach for most teams — the open weights matter for providers and platforms more than for laptops.
Frequently asked questions
When do Mistral Large 4's open weights arrive?
Mistral has committed to releasing them by the end of October 2026, along with architecture details and the license terms.
How much does the API cost?
$1.36 per million input tokens and $4.18 per million output tokens, in public preview on Mistral Studio.
Does Mistral Large 4 support Arabic?
The announcement mentions 160+ training languages without naming Arabic specifically. No Arabic proficiency is claimed; independent testing after the weights release will tell.
Is it better than GPT-6.1 Sol or Claude Opus?
On cybersecurity tasks Mistral claims a clear lead (82% on vulnerability patching, where US models reportedly refuse). In human coding evaluation it ranks second behind Claude Opus 5. There's no claim of overall supremacy — the right choice depends on your workload.
Where can I try it now?
In public preview via Mistral Studio (console.mistral.ai). No consumer chat release was announced at launch.
What to watch next
Three milestones will decide whether this announcement becomes a durable shift or an engineering footnote. First, the weights release and its license terms — a permissive license would spread the model across inference providers fast. Second, the first independent evaluations, especially on non-European languages and long-form writing, where the announcement offers no numbers. Third, whether Mistral ships the model into a consumer-facing chat product, which it did not announce at launch. Until then, the practical move is simple: run it on your real workload in the public preview, and compare output quality and cost against what you use today.
The bottom line
Mistral Large 4 matters because of the combination: trillion-parameter capability, open weights promised within weeks, frontier-class benchmarks in security and code, and pricing that pressures the entire market. If you build on large models, put it on your evaluation list for November. And if your daily work is producing Arabic and English content — writing, visuals, scheduling — you can run that whole pipeline from one place with ARWriter while the open-weights dust settles.